Tens of thousands of Nvidia GPUs sit idle in Meta’s Prometheus supercluster, just waiting for a failure
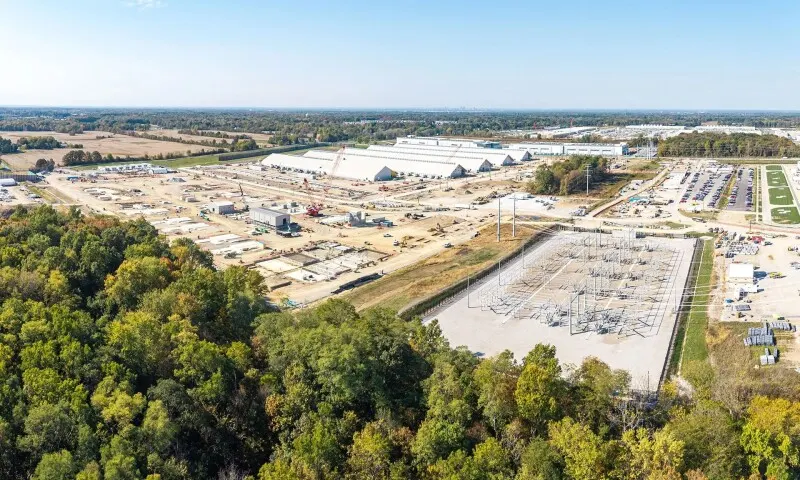
Meta has detailed how it is keeping its Prometheus AI supercluster running despite frequent hardware and software interruptions. The measures matter because training large models across vast numbers of GPUs can be disrupted by a single fault, forcing work to roll back to an earlier checkpoint.
Prometheus currently uses GB200 and GB300 systems, with 72 GPUs per NVLink domain but only 64 active at a time; the other eight serve as spares. Meta says interruptions fell from about 1,000 to 11 per day for every 8,000 GPUs over a year, a 99 per cent reduction. The planned system could eventually span multiple data centres and roughly one million accelerators.
- Eight of every 72 GPUs are held in reserve.
- Interruptions have fallen by 99 per cent in a year.
- Checkpointing helps protect long AI training runs.