0
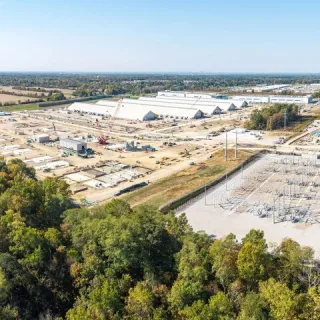
Tens of thousands of Nvidia GPUs sit idle in Meta’s Prometheus supercluster, just waiting for a failure
- Eight of every 72 GPUs are held in reserve.
- Interruptions have fallen by 99 per cent in a year.
- Checkpointing helps protect long AI training runs.
Meta has detailed how it is keeping its Prometheus AI supercluster running despite frequent hardware and software interruptions. The measures matter because training large models across vast numbers of GPUs can be disrupted by a single fault, forcing work to roll back to an earlier checkpoint. Prometheus currently…